Inference depends on model assets, customer data, retrieval systems, event streams, observability, billing, and analytics. When each workload runs on separate infrastructure, providers carry the added cost of integration, capacity management, protection, and operations.
VAST AI Operating System for Hyperscale AI Inference
Improve the Economics of Hyperscale AI Inference
Run hyperscale AI inference on a unified data platform that simplifies the infrastructure behind models, events, analytics, and operations, helping providers scale more efficiently as workloads, regions, and GPU fleets continue to grow.
The Hyperscale AI Inference Challenge
AI Inference Economics Carry the Cost of Data Complexity
Independent Capacity Planning
Each data platform needs its own headroom, replication, and growth plan. Capacity cannot be shared, making expansion more expensive and harder to predict.
Vectors Create a Second Data Plane
When embeddings live apart from source data, teams must synchronize metadata, permissions, lineage, retention, and deletion across two systems.
Event History Spans Two Stores
Request events flow through Kafka for live operations, then into a warehouse for SQL analysis. The same history consumes write bandwidth and capacity in two systems, with separate retention and replay paths.
Our partnership with VAST Data has grown more than 10x this past year and continues to accelerate — a reflection of how critical an AI data platform is to training and inference workloads on Crusoe Cloud.
Erwan Menard
SVP Product Management, Crusoe
Why Now
A New Data Architecture Changes the Inference Equation
For years, inference platforms have used separate systems for model delivery, request events, observability, and analytics. That shape becomes harder to sustain as providers grow at AI-market speed. Every launch expands several systems at once, while the time available to move data, reconcile records, and provision capacity keeps shrinking.
VAST's DASE architecture changes that model by separating the resources that serve and process data from the capacity that stores it. Multiple data services can run on a shared foundation while performance and capacity, guaranteed by QoS, scale independently.
Where infrastructure applications were once limited to the data copied into their own storage domain, they can now work from a shared platform. An engineer can follow a request ID and timestamps across events, deployment records, model-serving logs, and infrastructure telemetry without first waiting for each source to be exported into a common warehouse. An incident investigation no longer depends on separate copies arriving or staying synchronized before the engineer can establish what happened. At hyperscale, every delay affects too many models, regions, GPUs, and customers to wait for data copies.
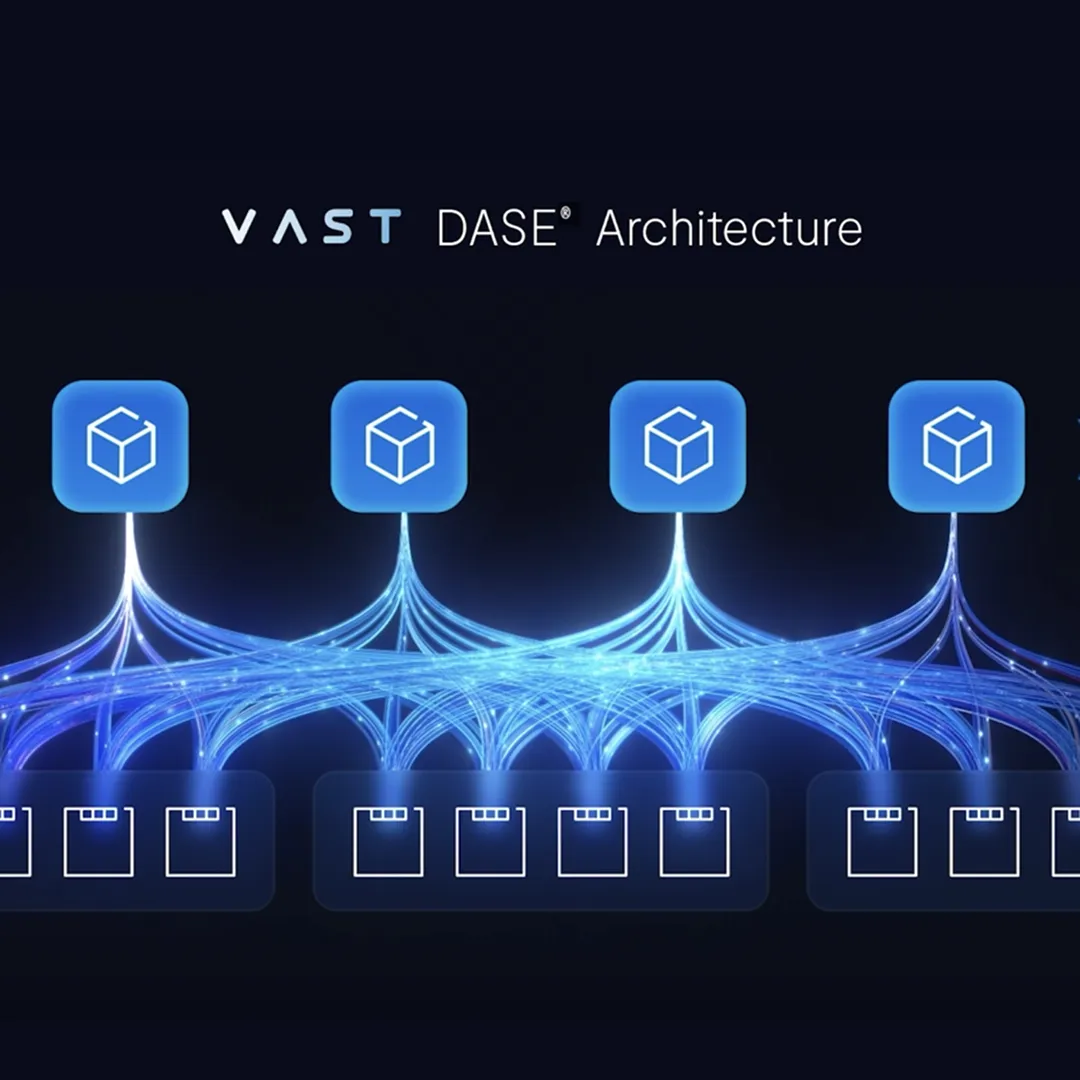
Proven Across AI Clouds
Scale on the Platform Leading AI Clouds Already Trust
VAST powers AI infrastructure for CoreWeave, Lambda, Nebius, Nscale, Mistral, Voltage Park, and other leading providers. Built on DASE, the VAST AI OS provides the common data foundation for cloud-scale inference economics.
Pool Capacity over Data Services
Share capacity, protection, and growth headroom across data services, while DASE lets performance scale independently as workload demands change.
Store Vectors With the Record
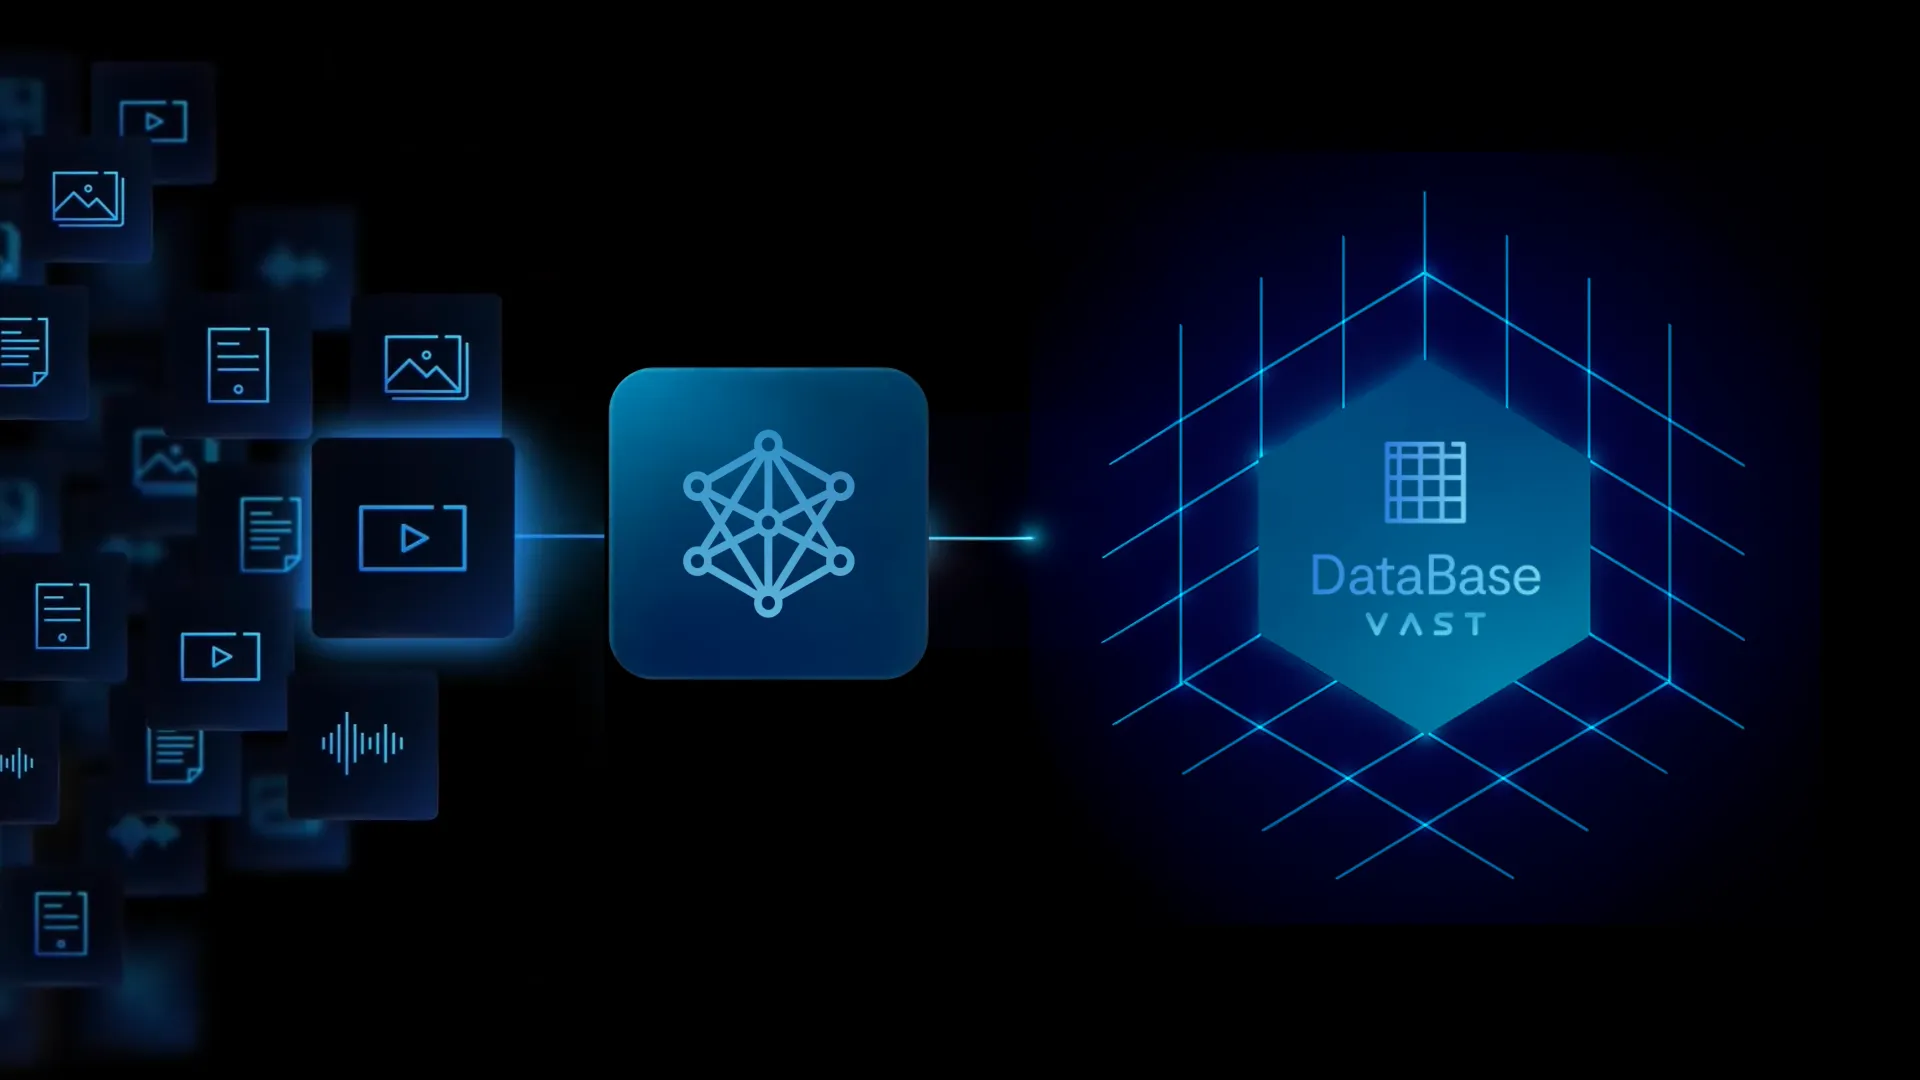
Store each embedding as a column beside its source record, then run similarity search and SQL filters through the same query engine, with no vector database to synchronize.
Query Events as Tables
Ingest events through the Kafka-compatible API, store them as VAST DataBase tables, and query the same event history with SQL without exporting it to a separate warehouse.
Reuse KV Across the Fleet
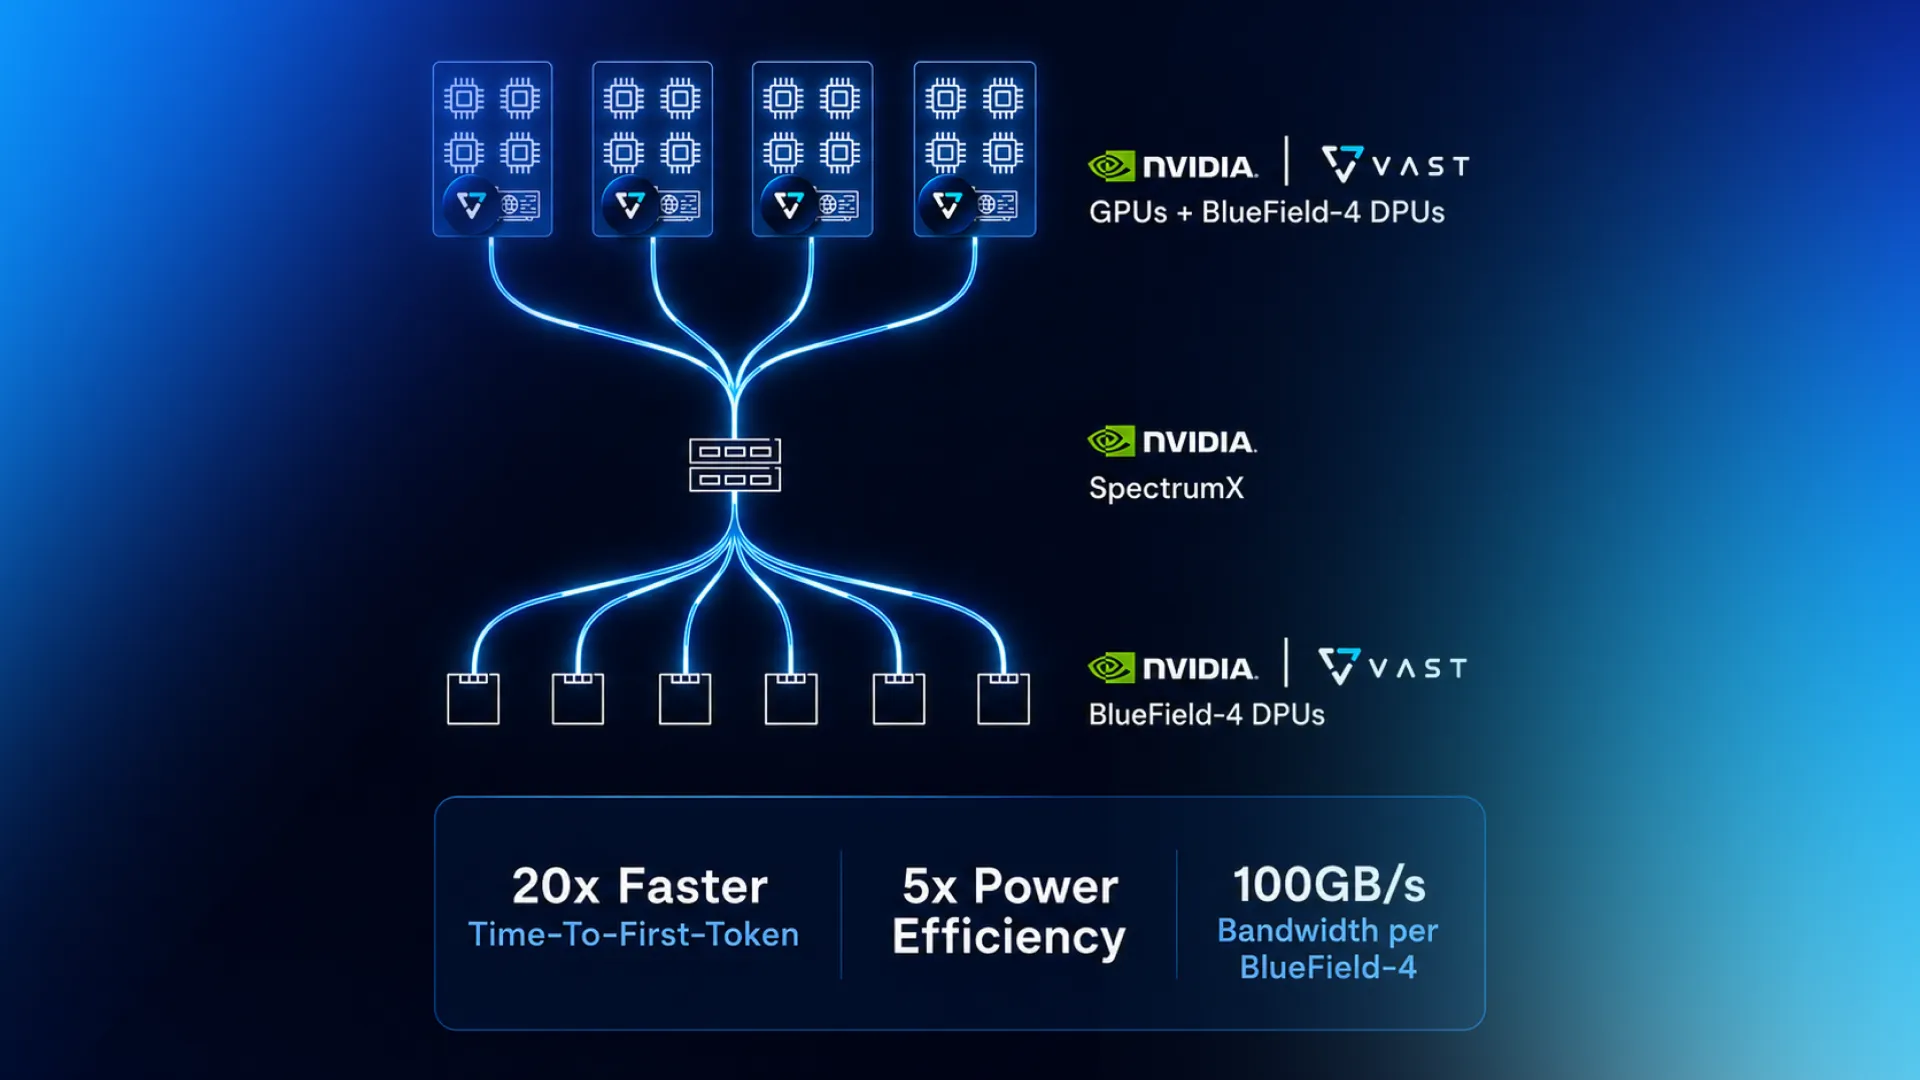
Let NVIDIA Dynamo or LMCache offload KV blocks to VAST, where any GPU can retrieve them instead of recomputing the same context during prefill.
Core Capabilities for Hyperscale Inference
See How VAST Simplifies the Inference Data Path
The architecture of the data plane shapes inference economics by determining how much infrastructure and operational work sits behind every token. VAST removes unnecessary system boundaries so capacity and data services can scale more efficiently.
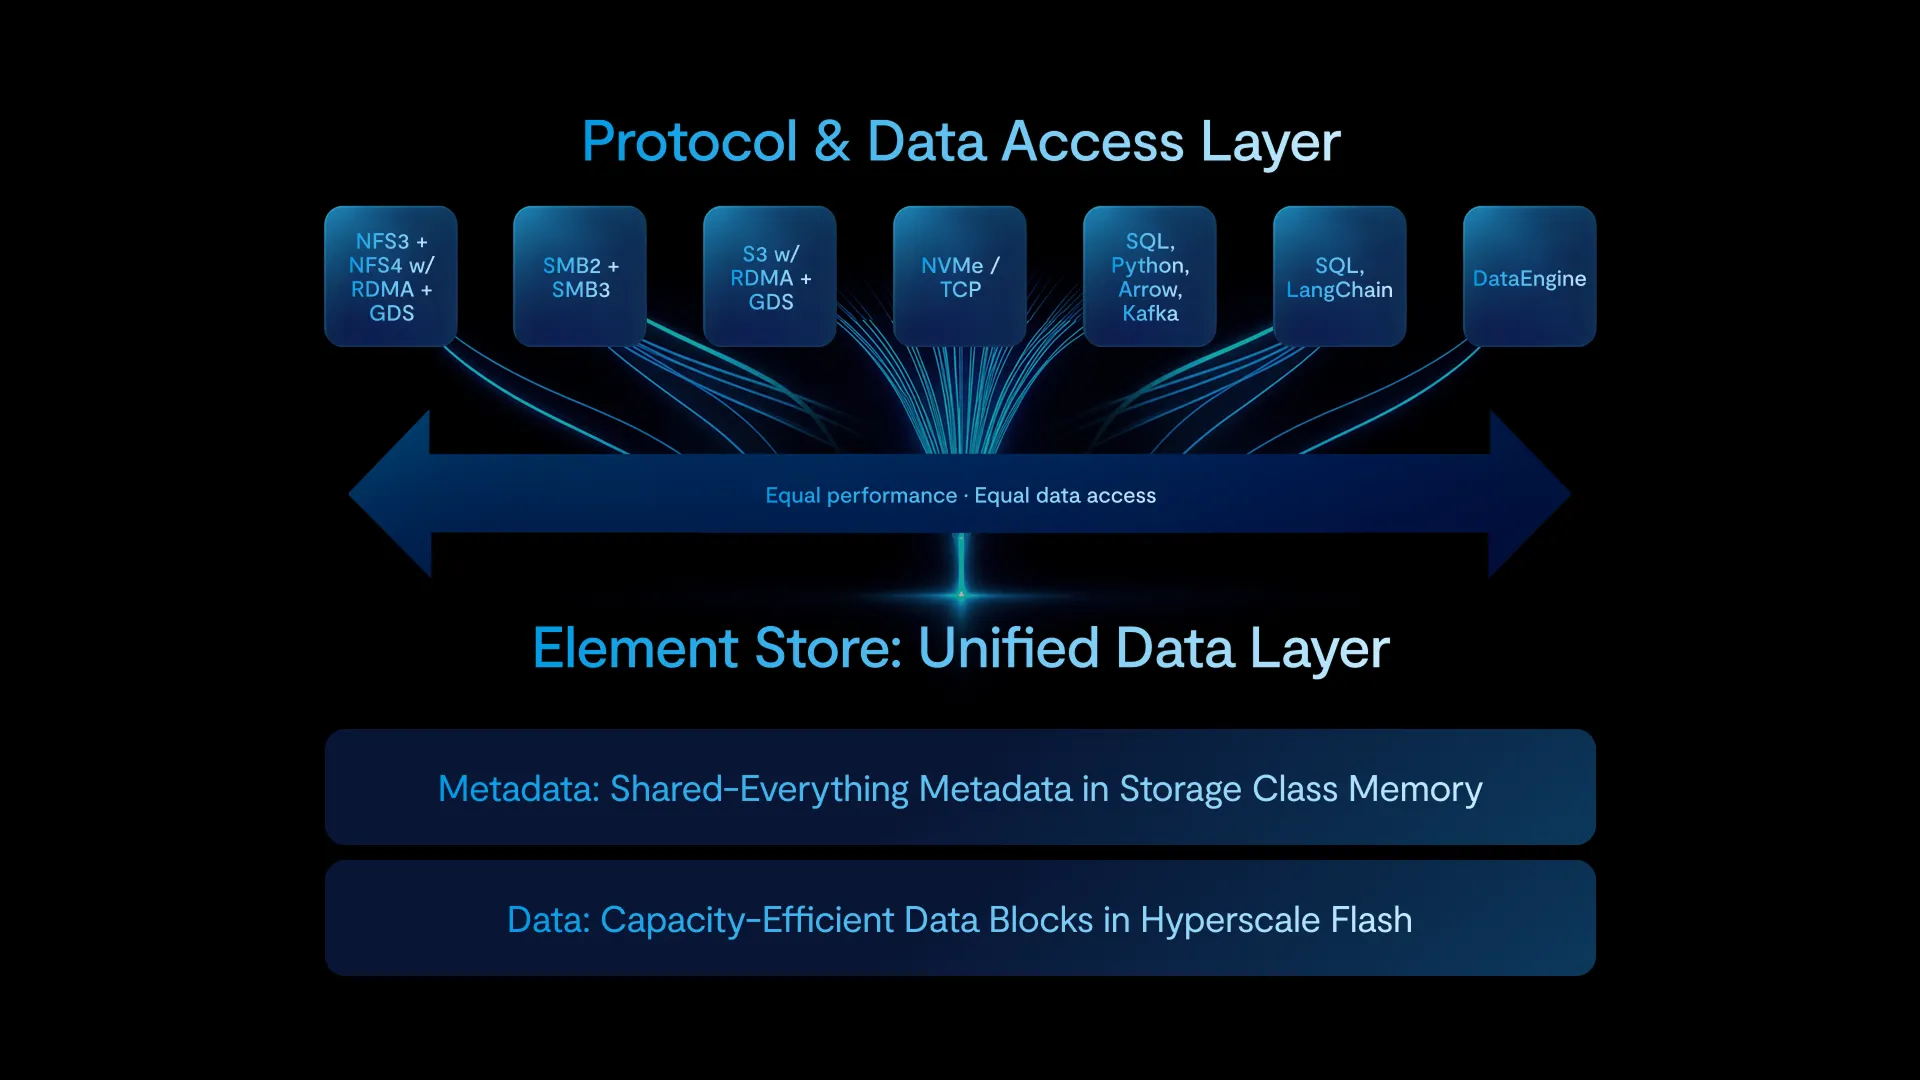
Serve One Element Through File and Object APIs
VAST Element Store assembles physical chunks into protocol-independent elements, serving the same data through NFS/SMB or S3. Both paths share one namespace, metadata model, and underlying data.
Explore the Element Store
How Does DataStore Improve Inference Economics?
Align Infrastructure Investment With Inference Demand
VAST DataStore uses DASE to separate data-serving performance from storage capacity, so providers can expand the resource that is actually constrained. Shared capacity and efficient data protection keep more of each infrastructure investment available to serve inference as demand changes.
Scale Only What the Workload Needs
Add CNodes when throughput is constrained and DBoxes when capacity is constrained, so infrastructure investment follows the actual bottleneck.
Pool Headroom Across Workloads
Run file, object, database, and KV workloads from one capacity pool, so unused headroom in one service can absorb growth in another instead of sitting stranded.
Industry Leading Efficiency
Innovative 146+4 erasure-code stripes (~3% parity overhead) and best in class data reduction delivers 2x more efficiency, so more purchased capacity remains available to inference workloads.
Use Case in Action
Serving Frontier Models Across Industries
From neoclouds renting GPUs by the token to enterprises serving their own fine-tuned models, VAST feeds inference where GPU efficiency decides the margin.