


Scaling from petabytes to exabytes exposes the limits of storage built for a single dimension. Peak performance is table stakes, and the strain surfaces elsewhere: unpredictable behavior, inflexibility under shifting demand, and infrastructure sprawl, all consuming scarce engineering attention.
VAST AI Operating System for Model Training
Meet the Data Demands of Frontier Training with VAST
Scale to exabytes of storage across file, object, block, and tabular data with a single, reliable platform. The VAST AI OS delivers the consistent performance demanded by frontier training across all modalities with over 99.999% uptime.
Storage at Scale for AI Training
At Frontier Scale, Storage Stops Getting Out of the Way
Infrastructure You Can’t Stop Watching
Storage that performs inconsistently quietly drains training goodput, and storage that becomes unresponsive stalls thousands of GPUs while engineers debug.
Isolation at the Cost of Utilization
Training demands on storage shift constantly. Packing preprocessing, data loading, and checkpointing onto one system risks interference, so multiple systems are deployed and capacity becomes stranded.
Operational Overhead and Sprawl
Engineering attention is the scarcest resource, yet growing tenfold often means tenfold the tuning, migrations, and separate silos, each with its own technology to master.
As we push the boundaries of large-scale model training, the foundation of our infrastructure becomes critical. VAST’s data platform enables us to efficiently manage and scale the massive datasets required to train frontier models, ensuring high performance and flexibility across our training pipelines.
Timothée Lacroix
Co-Founder and CTO, Mistral AI
The Cost of Inefficiency
Inefficiencies Compound with Model Growth
When a cluster held hundreds of accelerators and a model trained in days, storage inefficiency was absorbed. A few percent of lost goodput, an afternoon spent chasing a failure, a data migration managed by hand were all irritating, but they were rounding errors against the cost of the project. The same inefficiencies compound on clusters of tens of thousands of GPUs training for weeks at a time, where every hour of lost efficiency is an hour of idle capital.
VAST’s Disaggregated Shared-Everything (DASE) architecture allows performance and reliability to scale in lockstep with the workload. Rather than tuning for one dimension and absorbing the consequences in others, it delivers consistent throughput, graceful degradation, and strong isolation together.
The result is data infrastructure that behaves predictably when predictability matters the most. Production uptimes are five nines at minimum, an observed figure rather than an SLA target. Capacity is expanded online instead of during maintenance windows, performance is allocated rather than guessed, and engineer effort stays flat as the fleet grows.
The VAST AI Operating System
One Platform for Every Stage of Training
VAST manages all data that model training demands: raw datasets, model-ready training data, checkpoints, and the structured telemetry that tracks the job, in a single exabyte-scale namespace spanning file, object, block, and tables. That one system stays predictable under contention, grows without disruption, and takes no more to run at an exabyte than at a petabyte.
Sustain Performance at Scale
Achieve consistent bandwidth and IOPS throughout with fully distributed data and metadata. No random pauses, hangs, or other variation due to hotspots that arise in shared-nothing architectures.
Isolate Workloads
Performance is provisionable per workload and data is cryptographically isolated between tenants. Teams can share the same storage without compromising on throughput or governance.
Expand Without Downtime
Software upgrades, hardware refreshes, and capacity expansions all happen online. VAST is designed to never require downtime for maintenance.
Serve Every Protocol Natively
Unstructured training data and structured observability live on one system, each served natively. No protocol gateways to limit scalability and no separate data warehouses to manage.
Three Architectural Foundations
How Three Design Decisions Eliminate the Trade-Offs
Three design decisions do most of the work: separating compute from capacity, storing every data type as one kind of element, and enforcing isolation in software and hardware.
Disaggregated Shared-Everything Architecture
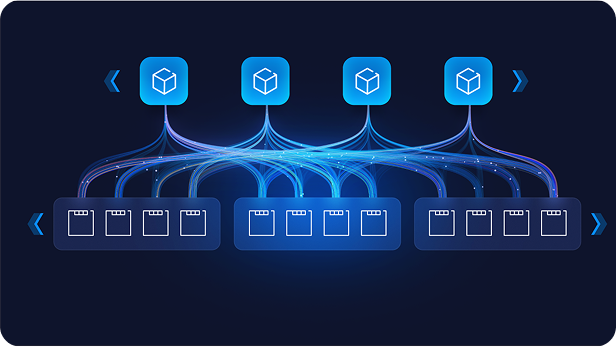
VAST disaggregates compute from persistence: stateless CNodes serve I/Os, DNodes store data on flash, and every CNode sees all data. This delivers truly linear performance scaling, and performance and capacity can be increased independently. Shared-everything ensures every byte remains available even as nodes go offline, delivering extreme resilience and downtime-free maintenance.
One Data Structure for All Protocols
The VAST Element Store is a data structure purpose-built for all-flash that stores all data types–file, object, block, and tables–in a unified structure. CNodes express elements as files, objects, block devices, and tables on request. Nothing is translated, protocols never desynchronize, and all accesses realize the full parallel performance of the DASE architecture.
Isolation Throughout the Stack
VAST enforces data separation at all levels of the stack, allowing limits to be set on bandwidth or IOPS per tenant, user, view or job ID. Pooling allows clients and subnets to be restricted to the performance of a subset of CNodes. These capabilities work with encryption at rest with external key management to ensure multiple tenants’ data and performance are fully isolated.
What does VAST DataStore do for model training?
The Unstructured Foundation Under Every Training Run
VAST DataStore stores and serves raw datasets, model-ready training data, and checkpoints via standard interfaces. Clients read and write data using high-performance NFS, S3, or other protocols, and workflows can switch protocols with no impact to scalability. All accesses are parallelized, and DataStore supports both TCP and RDMA transports.
Scale Capacity and Performance
A single namespace supports exabytes and trillions of files and objects, and performance scales with the compute serving it, so neither dimension limits the other.
Serve Every Protocol From One Copy
Developers interact with data as files, while preprocessing and data loading read the same bytes over S3, with no copy, conversion, or second namespace standing between the two stages.
Reduce Data Across the Exabyte Namespace
Similarity-based data reduction and global deduplication efficiently stores low-entropy data regardless of locality, delivering more usable bytes from a fixed pool of physical flash.