The Global Data Fabric for AI and Analytics
Unify data across edge-to-cloud environments in one global fabric that delivers all-flash performance and strict consistency for AI and analytics everywhere.
Trusted by the World’s Leading Data-Driven Organizations
Why Global Data Access Has Always Fallen Short
Legacy global-namespace systems promised anywhere-access but delivered latency, inconsistency, and lock-in. The VAST DataSpace breaks those limits with a global data fabric that unifies clusters worldwide while preserving strict transactional consistency.
“At a system level, VAST is built to handle the data bottleneck. It delivers the high throughput and predictable latency you need. But the real game changer for us and for our customers is VAST Global DataSpace.”

The Global Data Fabric for AI and Analytics
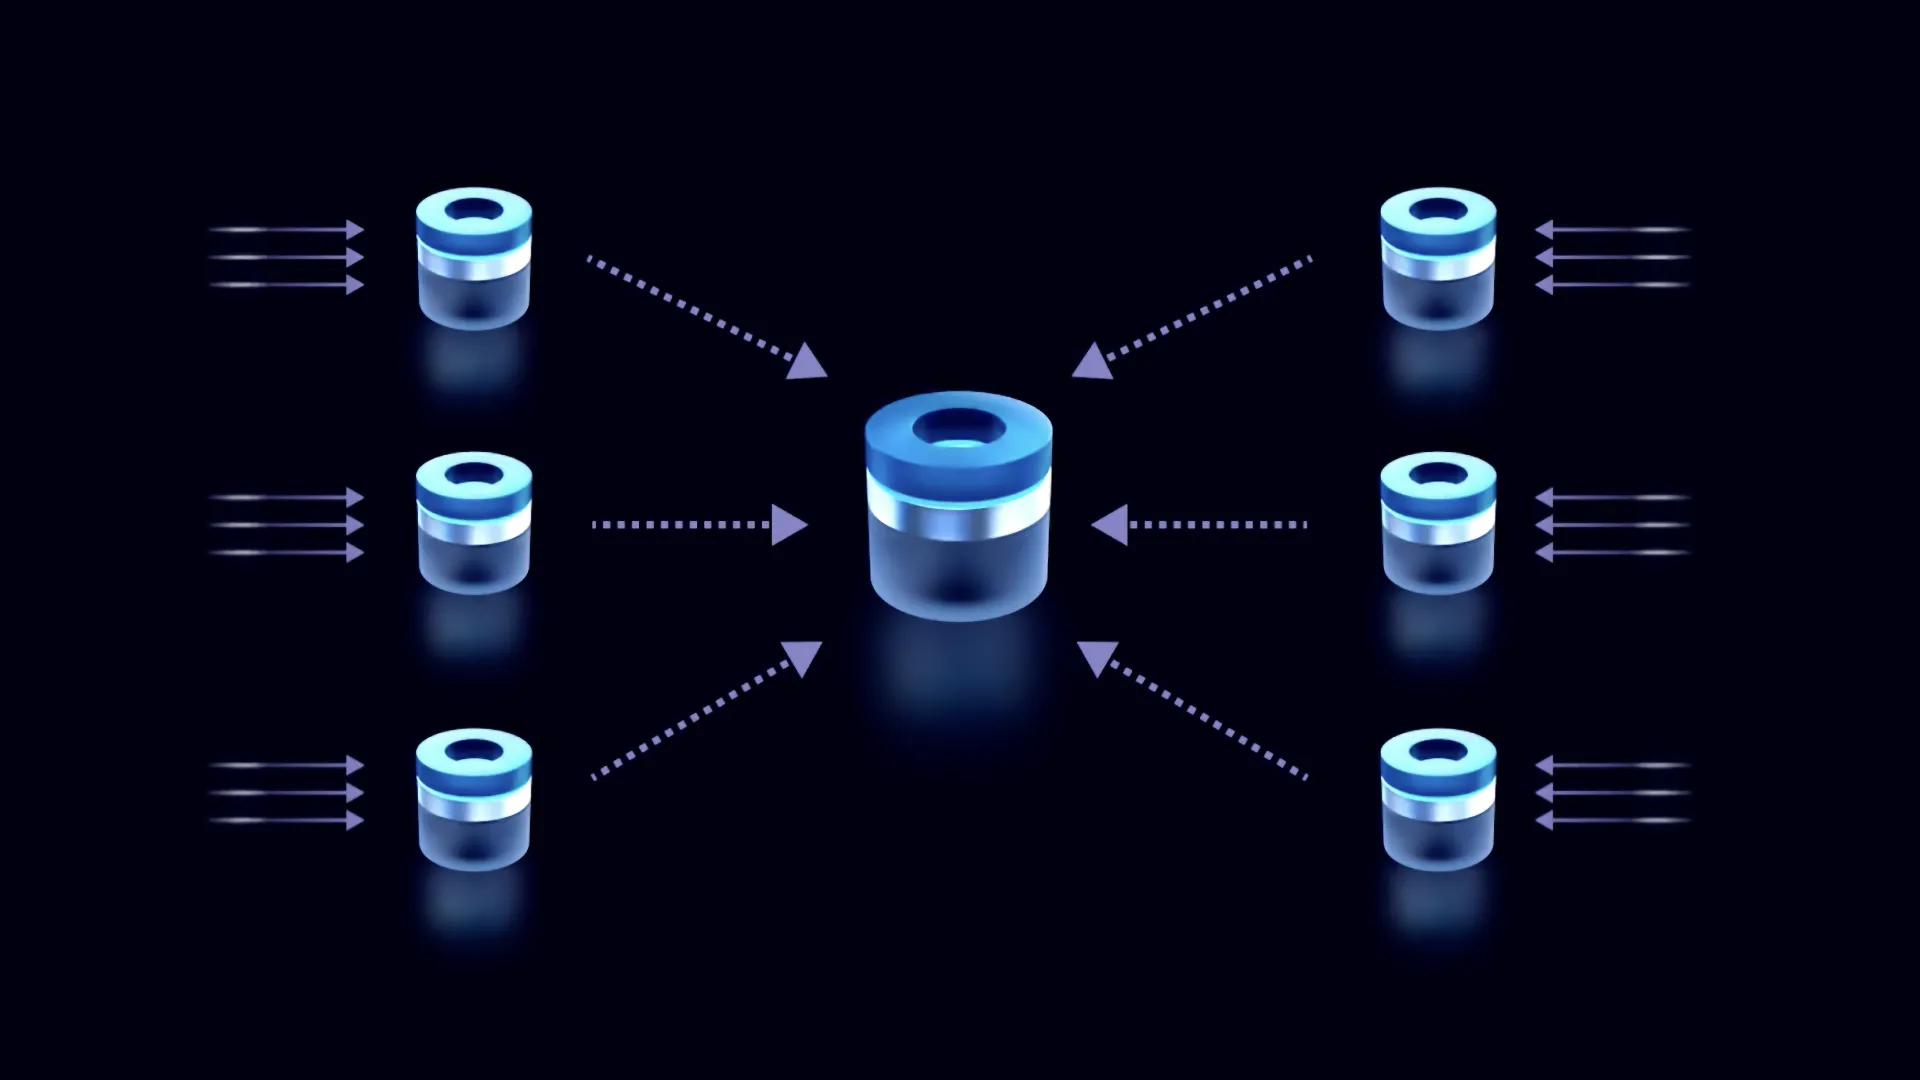
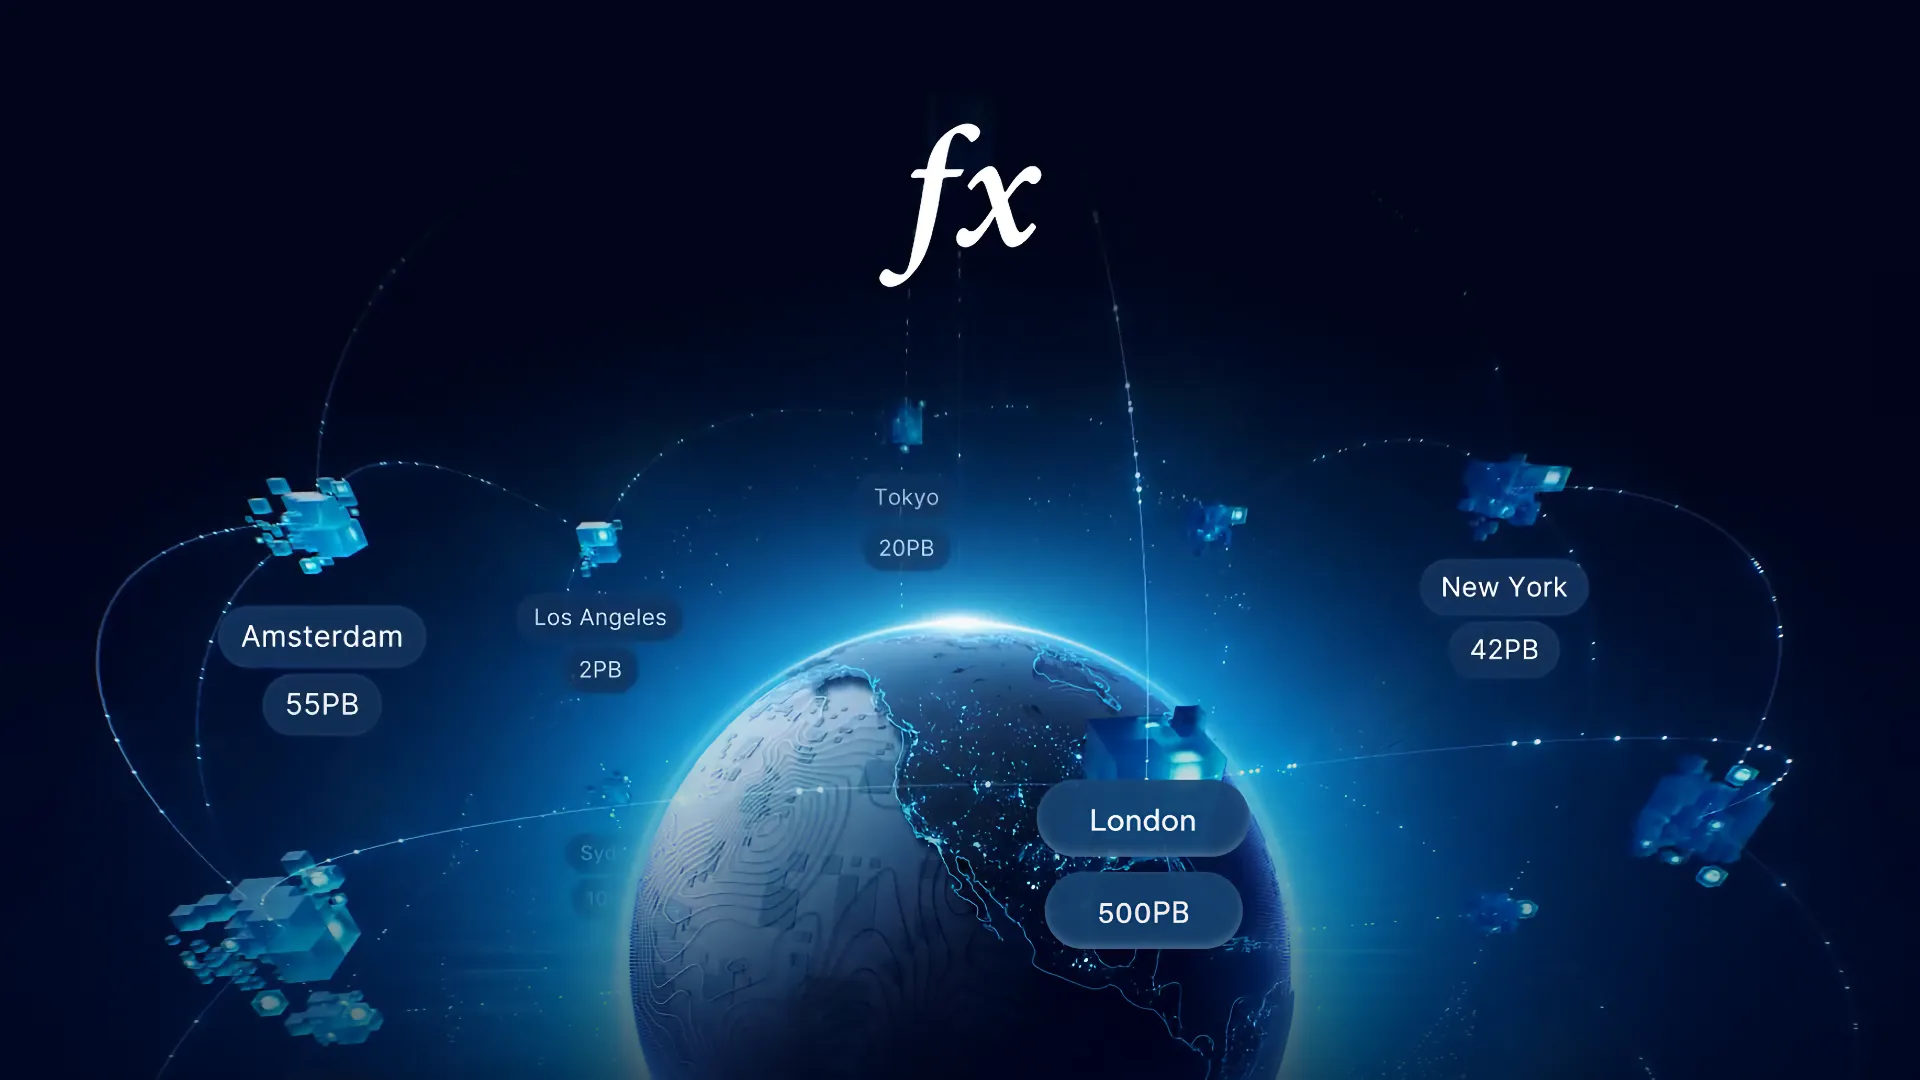
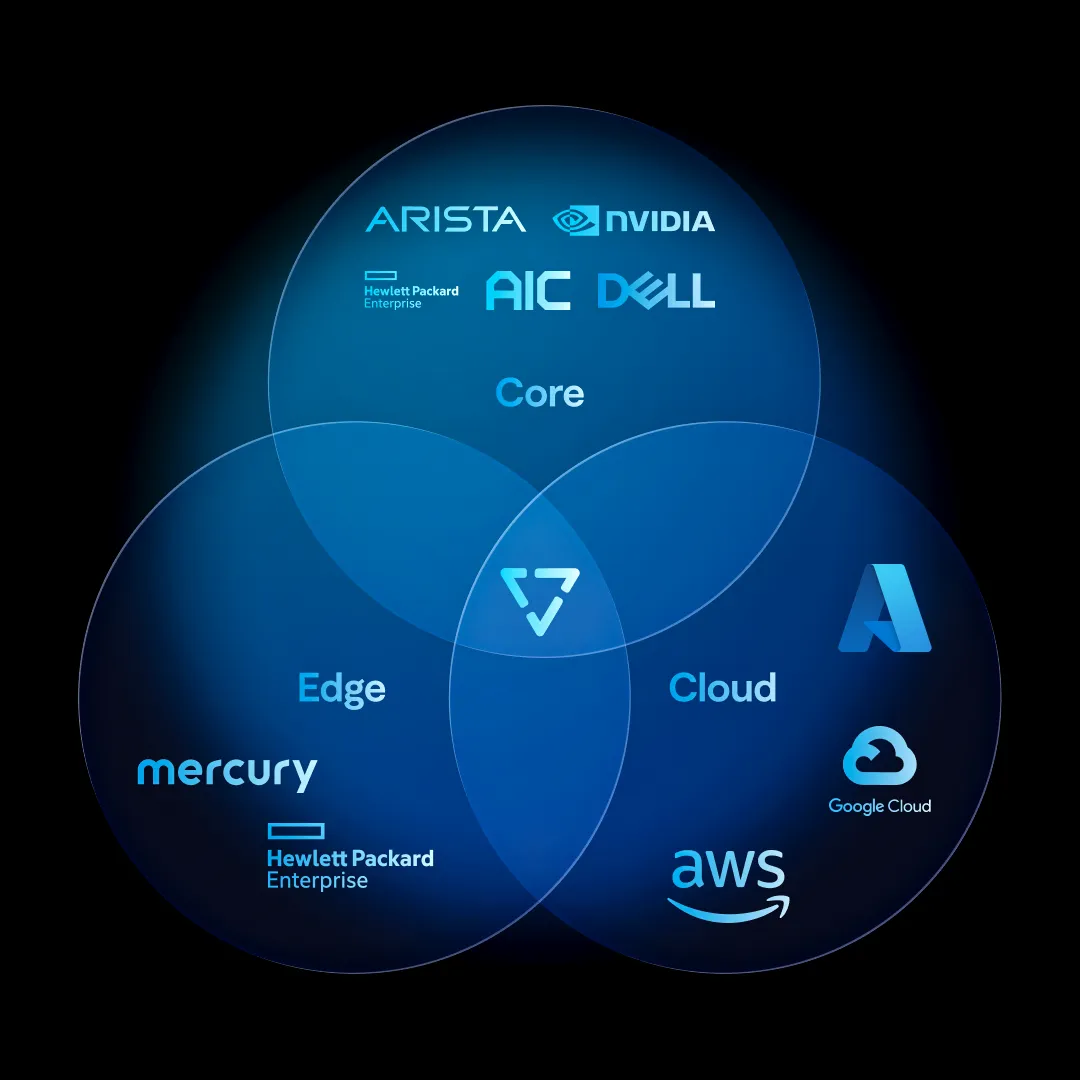
The VAST DataSpace unifies data across edge, core, and cloud in a single consistent fabric. It delivers all-flash access performance and synchronizes global data for AI and analytics at scale.
Cloud Clusters Enable Hybrid Workloads
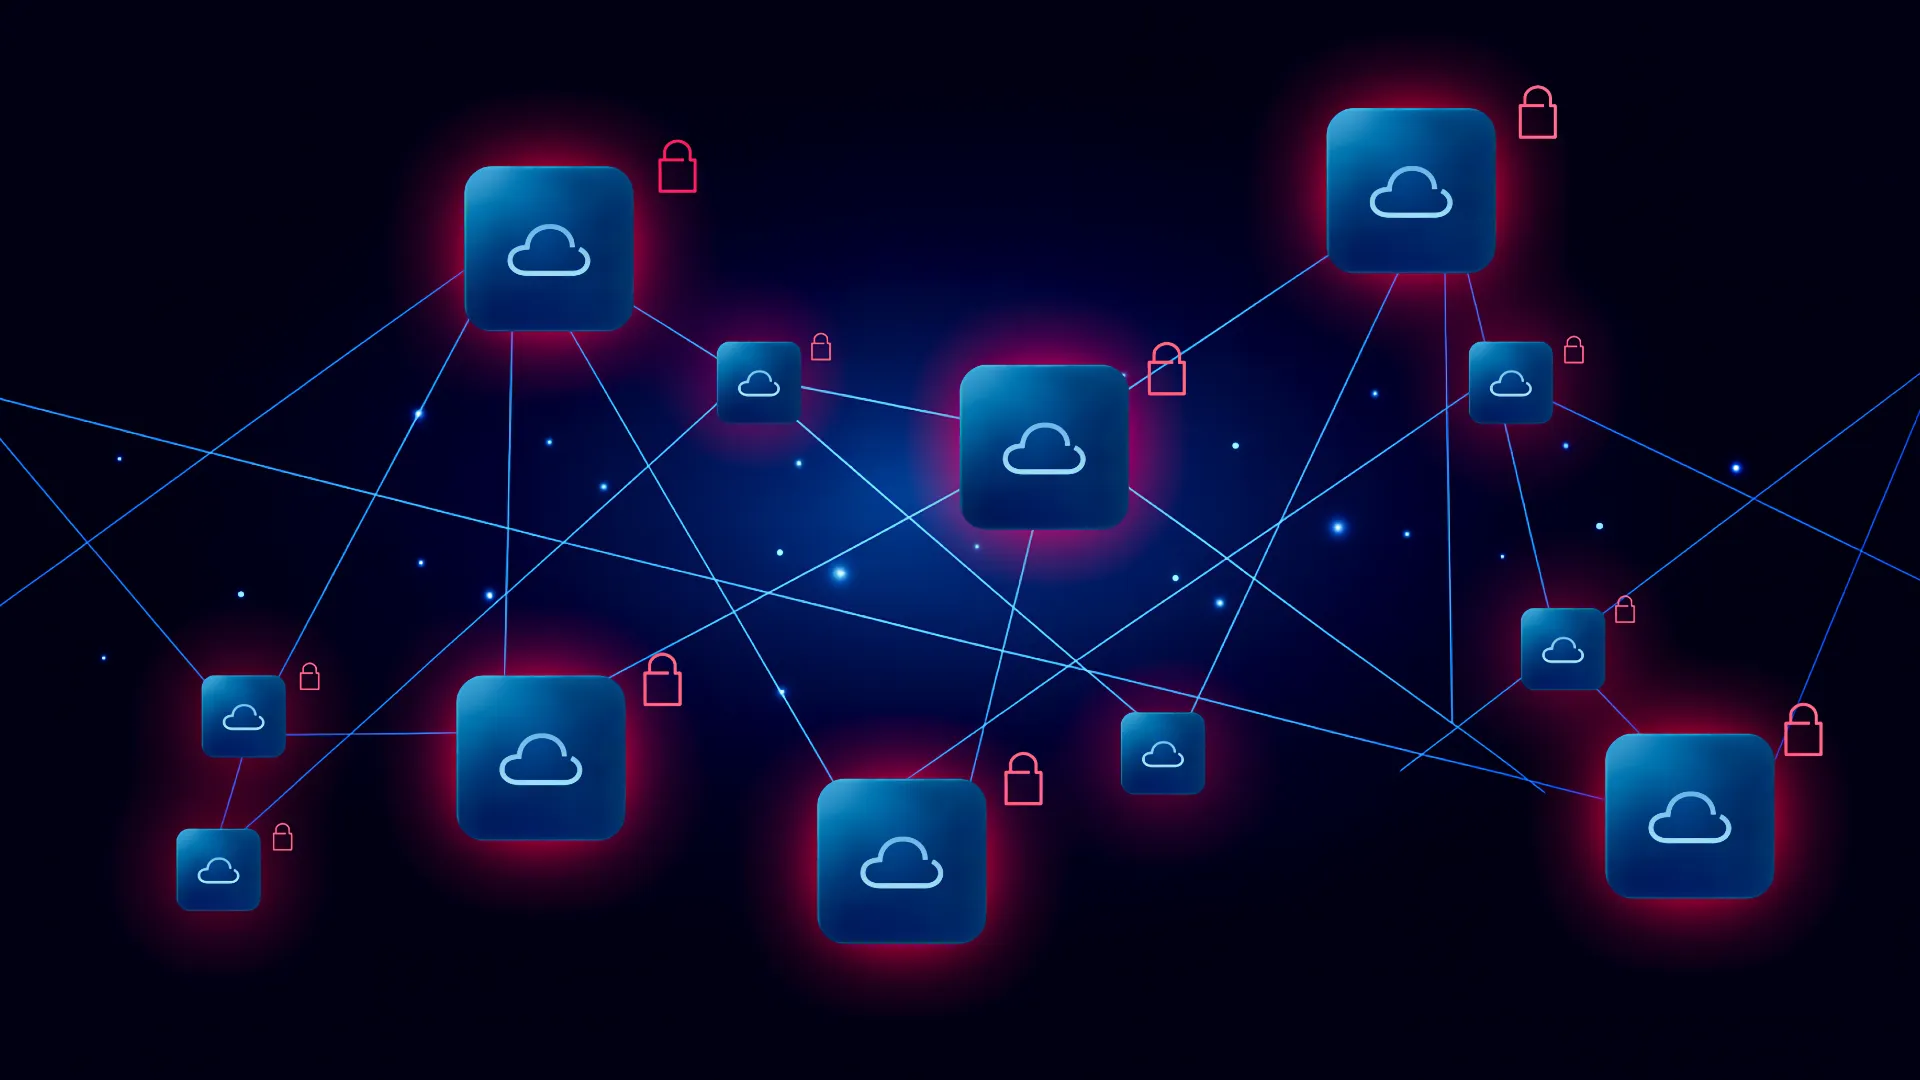
Full-featured VAST on Cloud clusters run on all major public clouds using cloud storage for durability and the VAST DataSpace to share data with other VAST clusters.
Say Goodbye to Data Gravity
Break free from data silos and locality limits. Simplify global operations and accelerate innovation with an AI-ready data platform that keeps information instantly available wherever compute happens.
Break the Tradeoff Between Performance and Consistency
Enjoy both all-flash access performance and global consistency at the same time. Eliminate latency and data conflicts and ensure every workload runs with the most current data everywhere.
Access Data Anywhere Without Compromise
Deliver high-performance access across edge-to-cloud environments, avoiding vendor lock-in and replication delays.
Adapt Synchronization to Your Business Needs
Align data movement, caches, and replicas with workload demand to reduce cost and complexity. Intelligent policies place data where it will be processed next, optimizing performance and resource utilization across global environments.
Ensure Global Consistency Without Sacrificing Performance
The VAST DataSpace lets you unify data from every location and enforce strict global consistency so AI and analytics operate with local performance and scale seamlessly to meet enterprise demands.
Asynchronous Replication for Data Durability
Protect data durability across sites without disrupting active workloads. Updates are transferred efficiently in the background, preserving performance and ensuring every dataset remains recoverable and up to date.
Synchronous Replication for RPO Zero
Mirror critical data in real time between clusters for instant recovery and uninterrupted operations. Every write is committed simultaneously across sites, ensuring zero data loss and maintaining edge-to-cloud data consistency for mission-critical workloads.
Snap‑to‑Object
Capture point-in-time images as S3-compatible objects to archive, clone, or recover instantly. Snap-to-Object reduces storage overhead and accelerates data protection by turning snapshots into durable, cloud-native assets.
Clone Snapshots Across the DataSpace
Create writable clones from any snapshot and share them instantly across clusters for parallel workstreams. Teams in different regions can analyze, edit, or train on the same data simultaneously without delay or duplication.
Global Namespace
Unify data across all sites into a single, consistent view that spans edge, core, and cloud environments. Predictive caching and intelligent prefetch keep information close to compute, eliminating silos and latency for globally distributed workloads.
Read and Write Leases
Guarantee strict consistency across all clusters without the latency of traditional file locks. Fine-grained read and write leases allow multiple sites to work with the same data simultaneously while always maintaining a single source of truth.
Workload-Aware Data Movement
Move data intelligently between clusters based on workload demand. Adaptive modes automatically fetch, pre-stage, or schedule synchronization to balance performance, cost, and efficiency.
Lazy Mode
Fetch and update data only when accessed, minimizing network traffic and cost for read-heavy or archival workloads. The VAST DataSpace caches frequently used data locally, eliminating unnecessary transfers and optimizing storage efficiency.
Eager Mode
Pre-stage data ahead of scheduled jobs so they start instantly and run at full speed. Workloads launch without delay as required datasets are positioned in advance for maximum throughput and utilization.
Metadata Prefetch
Make data folders feel local without the overhead of transferring data that may not be accessed. Allow remote workloads to select data quickly.
VAST Cloud Instances
Deploy VAST clusters natively in AWS, Azure, or Google Cloud to extend compute and data platform services elasticity. Ephemeral instances provide high-speed, read-optimized access, while persistent instances mirror writes for full data durability.
VAST on Cloud Clusters
Integrate cloud and on-premises environments into a unified global fabric. Workloads move seamlessly between locations, maintaining consistent performance and data integrity across every deployment.
Archive Clusters
Tier infrequently accessed data to cost-efficient cloud storage without changing workflows. Cold datasets remain instantly available through the same namespace, reducing expense while ensuring long-term accessibility.
Unified Management Plane
Manage every VAST cluster and cloud instance through a unified control plane for multicloud data management. Administrators can monitor health, set policies, and orchestrate replication or synchronization across the entire DataSpace environment.
Global Visibility and Control
Gain a consolidated view of performance and data flows across all locations. Alerts, analytics, and dashboards simplify operations and accelerate response times when workloads or clusters need attention.
Automated Policy Management
Define global rules for synchronization, access, and replication through the DataSpace control plane. Automation enforces these policies consistently across clusters and clouds, reducing manual effort and operational risk.
Explore the AI Operating System
Resources to Keep You Moving Forward
Introducing Global Access – VAST's Global Namespace
VAST's Global Access extends DataSpace across multiple clusters worldwide, enabling strictly consistent file access at every location with local performance—no sync delays or version conflicts.
The VAST DataSpace Explained | Build Beyond
VAST co-founder Jeff Denworth explains how the DataSpace creates a globally distributed namespace that enables consistent, high-performance data access across edge, on-premises, and cloud environments—breaking traditional trade-offs between locality and consistency.
Get the Facts About the VAST DataSpace
What is a global data fabric and why do I need one?
What is a global data fabric and why do I need one?
A global data fabric connects edge, core, and cloud environments into a single, consistent data space. It eliminates latency, inconsistency, and data silos caused by separate storage or replication systems. The VAST DataSpace delivers strict consistency and local-speed access everywhere, giving AI and analytics real-time visibility into enterprise data without the complexity of legacy global-namespace solutions.
How does the VAST DataSpace ensure performance and consistency across sites?
How does the VAST DataSpace ensure performance and consistency across sites?
The VAST DataSpace uses decentralized locks and leases to maintain strict consistency while allowing local-speed reads and writes at every location. Unlike systems that rely on eventual synchronization, it enforces real-time coherency through write leasing and intelligent caching. The result is immediate data access without WAN latency or conflicts; performance and consistency without compromise.
Can the VAST DataSpace support AI and analytics workloads globally?
Can the VAST DataSpace support AI and analytics workloads globally?
Yes. The VAST DataSpace delivers globally distributed data to wherever compute is available—on-premises, in the cloud, or at the edge. Its adaptive synchronization modes pre-stage or fetch data dynamically, ensuring every GPU, CPU, or analytics node runs on current information. The platform removes the need to move entire datasets, accelerating model training and inference at global scale.
How is the VAST DataSpace different from traditional replication or caching systems?
How is the VAST DataSpace different from traditional replication or caching systems?
Traditional replication systems copy whole datasets on a schedule, creating stale views and squandering bandwidth. The VAST DataSpace synchronizes only the blocks that change, using predictive prefetch and adaptive modes (Lazy, Eager, Schedule) to keep data aligned with compute demand. This architecture delivers continuous, fine-grained consistency with minimal network overhead.
Can I extend the VAST DataSpace into the public cloud?
Can I extend the VAST DataSpace into the public cloud?
Absolutely. VAST Cloud Instances run natively in AWS, Azure, and Google Cloud, allowing cloud compute to access on-premises data with local performance. Ephemeral instances cache data for burst workloads, while persistent instances mirror writes for full durability. Together, they extend your global namespace seamlessly into any cloud region without re-architecting applications.
Join the VAST Community
Discover how visionaries, architects, and technologists are shaping the future of data. Collaborate, learn, and grow with the minds building tomorrow's data infrastructure.